

Java8 Stream实现List对象属性去重
Java8中Stream的distinct基于equals和hashCode实现对象整体去重;对单个属性去重可借助map后distinct、TreeSet或自定义过滤器;多属性去重则通过TreeSet组合Comparator实现,这些方法覆盖了常见去重需求。
前言
在实际开发中,List集合去重是一个非常常见的需求——当数据量较大、来源分散时,重复记录很容易出现。很多时候需要的不只是复杂算法,而是一套干净、高效、可直接上手的解决方案。
本文整理了日常学习和实践中遇到的几种典型去重场景,重点围绕Java8 Stream流操作和TreeSet的天然去重特性展开。需要说明的是,方法只是工具,核心是在保证效率的前提下准确完成去重任务,不必拘泥于某一种固定写法。
正文
数据对象准备
为方便验证,先构造一个静态不可变的List,包含四条SyncBalance数据。其中部分字段完全重复,部分字段部分重复,可以覆盖多种去重场景。
private static final Listlist = asList( new SyncBalance(BigDecimal.ZERO, "12345678", 0, 1, "GGBond", 32, 0), new SyncBalance(BigDecimal.ZERO, "22345678", 0, 1, "GGBond", 32, 0), new SyncBalance(BigDecimal.ZERO, "22345678", 1, 1, "GGBond", 32, 0), new SyncBalance(BigDecimal.ZERO, "22345678", 1, 1, "GGBond", 32, 0) );
场景一:对象整体去重
最直接的需求:所有属性完全相同的记录视为重复,只保留一条。Stream自带的distinct()方法可以直接实现,它基于对象的equals()和hashCode()进行判断,前提是对象正确实现了这两个方法。
/**
 * 1. 对所有属性一样的数据进行去重
 */
public static void allColumnDistinct() {
    List allColumnDistinct = list.stream().distinct().collect(Collectors.toList());
}
场景二:单个属性去重(只返回属性值)
有时不需要保留整个对象,只需获取某个字段的去重列表,例如所有不重复的手机号。通过map先提取字段,再调用distinct()即可。
/**
 * 2. 对单个属性去重,只返回去重的属性
 */
public static void columnDistinct() {
    List columnDistinct = list.stream().map(SyncBalance::getMobile).distinct().collect(Collectors.toList());
}
场景三:单个属性去重(保留完整对象)
若需按某个字段去重并保留完整对象,Stream自带的distinct()无法支持。此时可采用TreeSet或自定义Predicate过滤器。以下提供三种常见写法。
/**
 * 3-1. 对单个属性一样的数据进行去重,下面是对`mobile`去重
 * 利用collectingAndThen + TreeSet,排序规则按mobile
 */
public static void oneColumnDistinctMethodOne() {
    List oneColumnDistinctMethodOne = list.stream().collect(Collectors.collectingAndThen(
            Collectors.toCollection(() -> new TreeSet<>(
                    Comparator.comparing(SyncBalance::getMobile))), ArrayList::new));
}
/**
* 3-2. 对单个属性一样的数据进行去重,下面是对`mobile`去重(通过自定义属性去重方法)
*/
public static void oneColumnDistinctMethodTwo() {
List oneColumnDistinctMethodTwo = list.stream().filter(distinctByKey(i -> i.getMobile())).collect(Collectors.toList());
}
/**
* list对象单个字段去重(自定义属性)
* @param keyExtractor 去重的对象字段
* @return
* @param
*/
public static Predicate distinctByKey(Function super T, ?> keyExtractor) {
Map
/**
 * 3-3. 对单个属性一样的数据进行去重,下面是对`mobile`去重
 * 直接用TreeSet逐个添加,简单暴力
 */
public static void oneColumnDistinctMethodThree() {
    TreeSet oneColumnDistinctMethodThree = new TreeSet<>(Comparator.comparing(i -> i.getMobile()));
    list.forEach(a -> oneColumnDistinctMethodThree.add(a));
}
场景四:多个属性组合去重
当去重条件涉及多个字段时,依然可以借助TreeSet,只需在Comparator中按多个字段进行拼接或链式比较即可。以下以手机号+状态两个字段为例。
/**
 * 4. 多个字段条件去重
 */
public static void twoColumnDistinct() {
    List twoColumnDistinct = list.stream().collect(Collectors.collectingAndThen(
            Collectors.toCollection(() -> new TreeSet<>(
                    Comparator.comparing(p -> p.getMobile() + ";" + p.getStatus()))), ArrayList::new));
}
验证方法
在主方法中依次调用上述去重方法,并在每个方法前后打印分隔标记,方便观察结果。
/**
 * 验证的main方法
 * @param args
 */
public static void main(String[] args) {
    allColumnDistinct();
    columnDistinct();
    oneColumnDistinctMethodOne();
    oneColumnDistinctMethodTwo();
    oneColumnDistinctMethodThree();
    twoColumnDistinct();
}
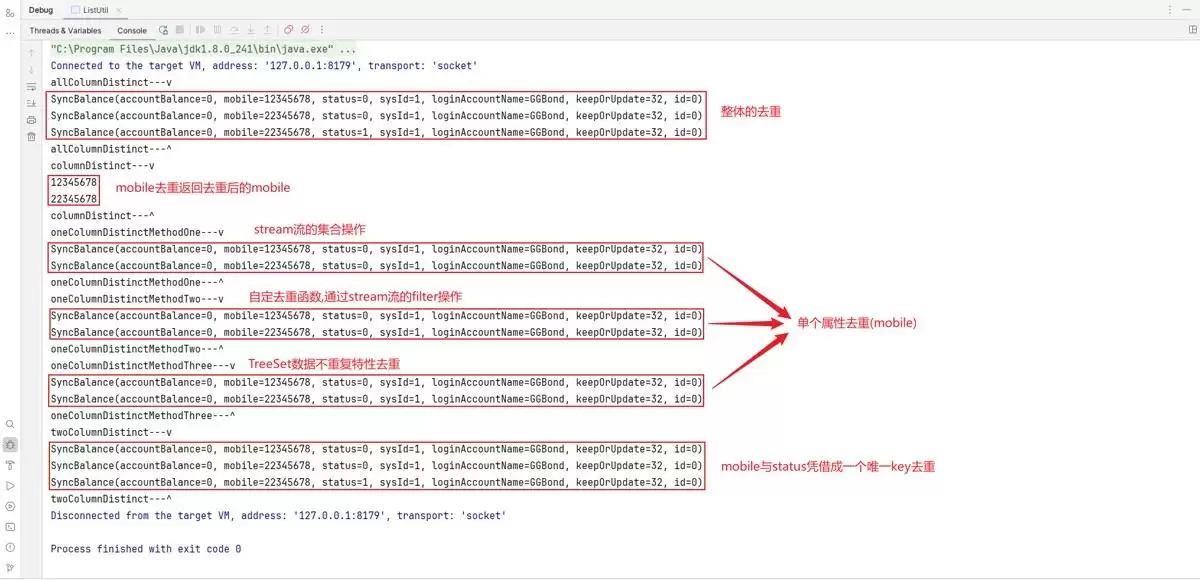
运行结果
allColumnDistinct---v
SyncBalance(accountBalance=0, mobile=12345678, status=0, sysId=1, loginAccountName=GGBond, keepOrUpdate=32, id=0)
SyncBalance(accountBalance=0, mobile=22345678, status=0, sysId=1, loginAccountName=GGBond, keepOrUpdate=32, id=0)
SyncBalance(accountBalance=0, mobile=22345678, status=1, sysId=1, loginAccountName=GGBond, keepOrUpdate=32, id=0)
allColumnDistinct---^
columnDistinct---v
12345678
22345678
columnDistinct---^
oneColumnDistinctMethodOne---v
SyncBalance(accountBalance=0, mobile=12345678, status=0, sysId=1, loginAccountName=GGBond, keepOrUpdate=32, id=0)
SyncBalance(accountBalance=0, mobile=22345678, status=0, sysId=1, loginAccountName=GGBond, keepOrUpdate=32, id=0)
oneColumnDistinctMethodOne---^
oneColumnDistinctMethodTwo---v
SyncBalance(accountBalance=0, mobile=12345678, status=0, sysId=1, loginAccountName=GGBond, keepOrUpdate=32, id=0)
SyncBalance(accountBalance=0, mobile=22345678, status=0, sysId=1, loginAccountName=GGBond, keepOrUpdate=32, id=0)
oneColumnDistinctMethodTwo---^
oneColumnDistinctMethodThree---v
SyncBalance(accountBalance=0, mobile=12345678, status=0, sysId=1, loginAccountName=GGBond, keepOrUpdate=32, id=0)
SyncBalance(accountBalance=0, mobile=22345678, status=0, sysId=1, loginAccountName=GGBond, keepOrUpdate=32, id=0)
oneColumnDistinctMethodThree---^
twoColumnDistinct---v
SyncBalance(accountBalance=0, mobile=12345678, status=0, sysId=1, loginAccountName=GGBond, keepOrUpdate=32, id=0)
SyncBalance(accountBalance=0, mobile=22345678, status=0, sysId=1, loginAccountName=GGBond, keepOrUpdate=32, id=0)
SyncBalance(accountBalance=0, mobile=22345678, status=1, sysId=1, loginAccountName=GGBond, keepOrUpdate=32, id=0)
twoColumnDistinct---^
结尾
集合去重的思路远不止Stream和TreeSet这两种,只要能保证效率和正确性,使用HashSet、LinkedHashMap甚至数据库去重都是可行的。关键是理解每种场景下“去重”的具体含义——是整个对象、某个字段、还是字段组合?明确需求,选对工具,代码自然干净利落。